Research paper ISM2022 2022
Explaining video summarization based on the focus of attention
Shows which video fragments influence a summary using signals from the model's attention mechanism.
IEEE Int. Symposium on Multimedia (ISM) 2022 December 2022
Evlampios Apostolidis*, Georgios Balaouras*, Vasileios Mezaris, Ioannis Patras
* Equal contribution
Abstract
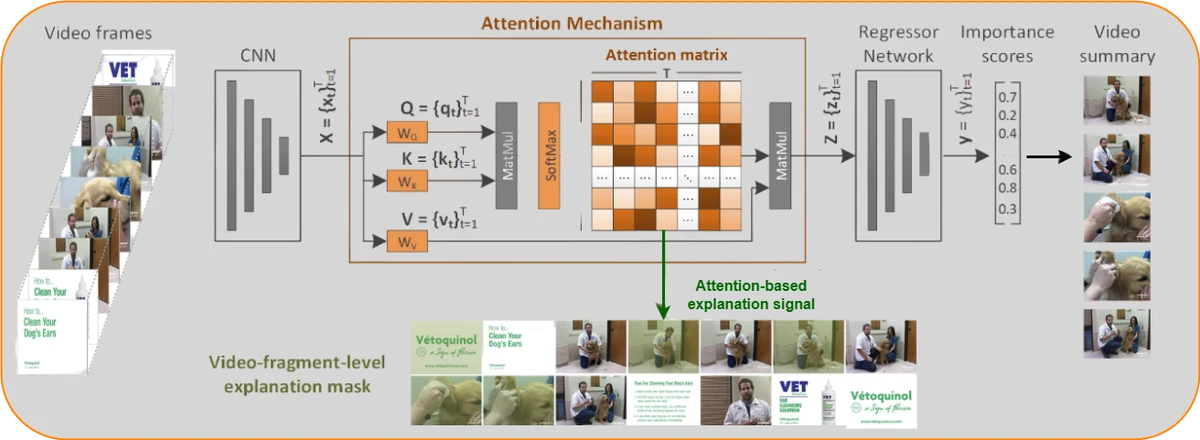
In this paper we propose a method for explaining video summarization. We start by formulating the problem as the creation of an explanation mask which indicates the parts of the video that influenced the most the estimates of a video summarization network, about the frames' importance. Then, we explain how the typical analysis pipeline of attention-based networks for video summarization can be used to define explanation signals, and we examine various attention-based signals that have been studied as explanations in the NLP domain. We evaluate the performance of these signals by investigating the video summarization network's input-output relationship according to different replacement functions, and utilizing measures that quantify the capability of explanations to spot the most and least influential parts of a video. We run experiments using an attention-based network (CA-SUM) and two datasets (SumMe and TVSum) for video summarization. Our evaluations indicate the advanced performance of explanations formed using the inherent attention weights, and demonstrate the ability of our method to explain the video summarization results using clues about the focus of the attention mechanism.
The paper in brief
- Problem: A summary identifies important frames but does not show which parts of the video drove those estimates.
- Approach: Form an explanation mask from the summarization network’s attention signals, then test it by replacing video segments.
- Finding: On SumMe and TVSum, explanations based on the network’s own attention weights performed well at identifying influential segments.